Sockpuppet Detection in Hebrew Wikipedia: NLP & Authorship Analysis
A multimodal authorship-analysis framework for Hebrew Wikipedia that combines lexical, stylistic, and semantic evidence to rank pairs of accounts for further human investigation.
Can Hebrew sockpuppet pairs be identified from complementary authorship signals?
The project treats sockpuppet detection as a pairwise authorship problem. Instead of relying on a single textual representation, it combines three different views of the same users: lexical overlap, stable writing habits, and contextual semantic similarity.
The system is intended as decision support rather than an automatic banning mechanism. It assigns suspicion probabilities that can help investigators prioritize pairs for human review.
Hebrew-specific challenge
- Morphologically rich word forms
- Attached prefixes
- Spelling variation
- Mostly unvocalized text
- Topic similarity that can imitate authorship similarity
Three signals, one pair-level classifier.
Wikipedia comments are aggregated into user-level text representations. TF-IDF word n-grams model lexical similarity, stylometric features capture writing habits, and heBERT embeddings provide a semantic signal. A Random Forest combines the three similarities into a final pair-level prediction.
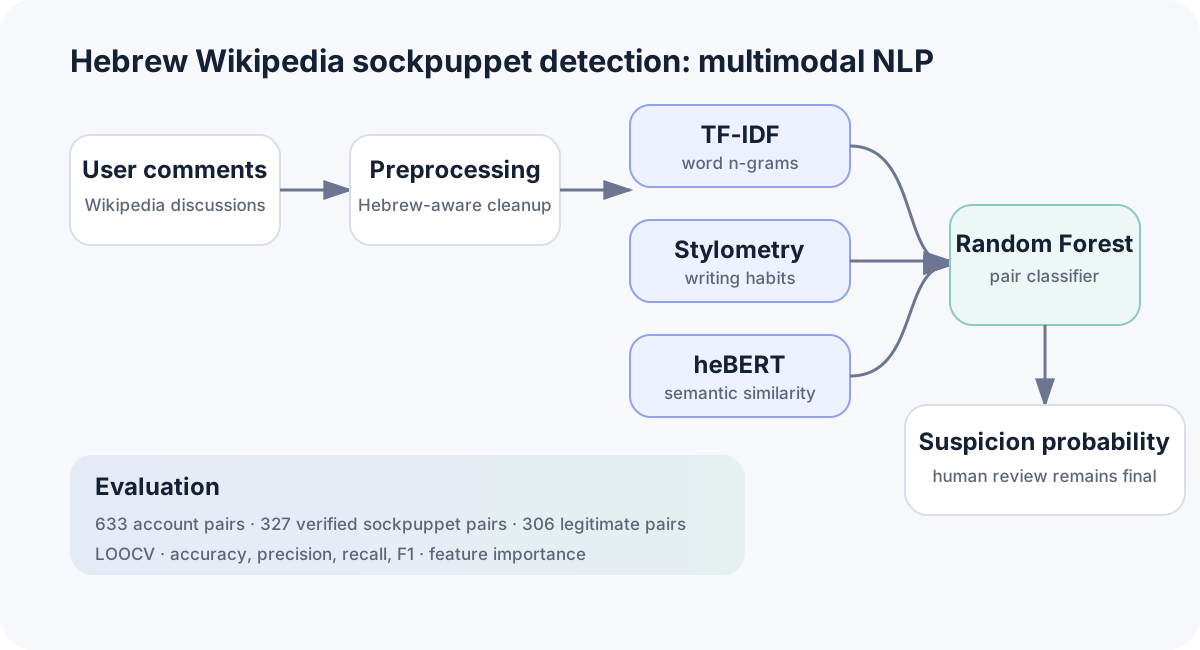
Leave-One-Out Cross-Validation on verified and legitimate pairs.
Dataset
The reported evaluation contains 633 account pairs: 327 verified sockpuppet pairs and 306 legitimate pairs.
Classification performance
Overall accuracy was 77%. For the sockpuppet class, precision was 0.81, recall 0.72, and F1-score 0.76.
Feature contribution
Feature-importance analysis attributed 47.33% of decision importance to semantic features, 33.00% to stylometry, and 19.67% to TF-IDF.
Discovery phase
The trained model was subsequently applied to undocumented account pairs, with pairs receiving predicted probability of at least 70% flagged for further investigation rather than treated as confirmed identities.
Complementary evidence is more useful than a single authorship cue.
Lexical similarity can be affected by topic, stylometry can be intentionally altered, and semantic similarity can be high simply because two legitimate editors discuss the same subject. The project therefore frames the three representations as partially independent evidence sources whose combination is more informative than any one signal in isolation.
The reported results are promising for triage and investigation, but they do not justify treating the classifier as definitive proof that two accounts belong to the same person.
Methods
- TF-IDF word n-grams
- Stylometric similarity
- heBERT embeddings
- Random Forest classification
- Leave-One-Out Cross-Validation
- Precision, recall and F1 analysis
A Hebrew-language authorship problem with an explicit human-in-the-loop interpretation.
The project demonstrates a practical pipeline from Wikipedia text collection to pairwise ranking while retaining a clear distinction between statistical suspicion and verified identity.